Running Jobs
Batch jobs (sbatch)
sbatch is a slurm command which submits a batch job to the queue. You can pass a job script or job recipe as a file to the command, or, if no file name is
given, sbatch reads the script from standard input. A batch script can include options preceded by #SBATCH lines
before any executable commands. sbatch stops processing #SBATCH directives after the first non-comment,
non-whitespace line.
Job scripts
A job script (also called a submit file) is a plain text file where you request cluster resources and list, in order, the
commands you want to run. The script is passed to sbatch, which submits it to the Slurm scheduler.
Below is a Slurm job script example. The file name used in this example is slurm_test.sub.
Job Example
#!/bin/bash

#SBATCH --partition=main               #Selecting the partition
#SBATCH --job-name="hello"              #Name of job (displayed in squeue)
#SBATCH --nodes=1                       #Number of nodes
#SBATCH --ntasks-per-node=10            #Number of tasks per node
#SBATCH --time=00:05:00                 #Maximum time for job to run
#SBATCH --mem=2G                        #Memory per node
#SBATCH --output=slurm.%N.%j.out        #Output file for stdout (optional)
#SBATCH --error=slurm.%N.%j.err         #Error file for stderr (optional)

cd $SLURM_SUBMIT_DIR                    #Change to submission directory

conda activate myenv                    #activate conda env

python helloworld.py                    #Run python file
The #SBATCH directives in your job script define the resources requested for compute jobs. Use only the options you
need to describe your requirements. If you do not specify resources using #SBATCH, standard defaults are assigned to the
job. #SBATCH lines must appear at the top of the script with no blank lines between them.
The general format is: #SBATCH --<option>=<value>.
To run the example job yourself, save the contents of this example to a file called `` slurm_test.sub`` and submit ite from a login node with sbatch slurm_test.sub.
Tip
More examples are available in the Slurm Examples section.
sbatch options
Some common options you might want to use in your job submit file:
#SBATCH --nodes=<number>              # Number of nodes requested (useful for multi-node workloads such as MPI)
#SBATCH --ntasks-per-node=<number>    # Number of tasks (processes) to run per node; common for MPI ranks per node
#SBATCH --ntasks=<number>             # Total number of tasks across all nodes
#SBATCH --cpus-per-task=<number>      # CPU cores per task (threads per task)
#SBATCH --mem=<size>                  # Total memory per node (e.g. 4G)
#SBATCH --mem-per-cpu=<size>          # Memory per CPU core (e.g. 2G)
#SBATCH --constraint=<attribute>      # Node property to request (e.g. cpu_intel, gpu_h200)
#SBATCH --partition=<partition_name>  # Request specified partition or queue
#SBATCH --job-name=<myjobname>        # Name of Job
#SBATCH --error=<slurm.err>           # Specify file for stderr
#SBATCH --output=<example.out>        # Specify file for stdout
#SBATCH --time=<hh:mm:ss>             # Maximum wall time (job terminates when this limit is reached)
#SBATCH --exclusive                   # Exclusive access to node
#SBATCH --gpus-per-node=<number>      # Number of GPUs requested per node
Slurm environment variables
$SLURM_XXXX are useful built-in environment variables from Slurm that you can put into your scripts to make them more
automated and transferable. In the helloworld example above, the Slurm environment variable $SLURM_SUBMIT_DIR is used
so the job changes to the submission directory before running any commands.
Environment Variables:
$SLURM_JOB_ID          # Job ID
$SLURM_SUBMIT_DIR      # Directory where the job was submitted
$SLURM_JOB_NODELIST    # List of allocated host names
$SLURM_NTASKS          # Total number of tasks
$SLURM_CPUS_PER_TASK   # CPU cores per task
$SLURM_ARRAY_TASK_ID   # Index for array task
Submit a batch job
Once you have created your job script (submit file), submit it from a login/submit node using
sbatch <job_script>. For example, to submit slurm_test.sub:
[abc123@costar-login01 ~]$ sbatch slurm_test.sub
Submitted batch job 9442
Once submitted, your job is allocated a job ID number, which is used to reference and manage the job (e.g. with
squeue).
Tip
To learn how to cancel a running job or use other job management commands, see Job Management
Interactive jobs (srun)
An interactive job connects you to a shell on the allocated compute node(s) so you can run commands directly and see output immediately. This is useful for debugging and testing commands before you submit a non-interactive batch job, where the job runs in the background and writes output to files.
Note
An interactive job will not bypass the queue, the job will be submitted to the slurm scheduler and will be assigned to a compute node in the same way as a batch job.
Submit an interactive job
To run an interactive job you will need to use the srun command.
This is used to get slurm to allocate resources after which you can ssh into the node(s) allocated to do interactive work.
Resources for interactive sessions can be allocated using the same options as sbatch shown in sbatch options
by adding them as arguments to the srun command e.g. srun --<option>=<value> --<option>=<value> --pty bash.
[abc123@costar-login01 ~]$ srun -N 1 --exclusive --constraint=cpu_intel --time=02:00:00 --pty bash
[abc123@costar01 ~]$ squeue -u abc123
            JOBID PARTITION     NAME     USER ST       TIME  NODES NODELIST(REASON)
            108098    shared     bash   abc123  R       0:05      1 costar01
[abc123@costar01 ~]$ exit
exit
[abc123@costar-login01 ~]$ squeue -u abc123
            JOBID PARTITION     NAME     USER ST       TIME  NODES NODELIST(REASON)
[abc123@costar02 ~]$
srun can also be used to run commands interactively and then immediately close the allocation.
This can be done by putting a command at the end of the srun line, for example
srun --<option>=<value> --<option>=<value> <command to run>.
[abc123@costar-login01 ~]$ srun -N 1 --constraint=cpu_intel --time=02:00:00 echo "hello world"
helloworld
Array jobs (submitting a batch of jobs)
Often you may need to submit many similar jobs over a list or index. In these cases you should avoid creating and submitting hundreds of separate job scripts. Instead, submit a job array from a single script. Array jobs let you submit and manage a set of related tasks in a compact way.
The example below submits array indices 1 to 16 using #SBATCH --array=1-16. The index is then available in
$SLURM_ARRAY_TASK_ID inside the script.
#!/bin/bash

#SBATCH --job-name=array
#SBATCH --array=1-16              #Array indices/range for $SLURM_ARRAY_TASK_ID
#SBATCH --time=01:00:00
#SBATCH --partition=main
#SBATCH --ntasks=1
#SBATCH --mem=4G
#SBATCH --error=array_%A_%a.err   #Error file labeled by job ID and task index

# Print the task ID.
echo "My SLURM_ARRAY_TASK_ID: " $SLURM_ARRAY_TASK_ID > test_"$SLURM_ARRAY_TASK_ID"
In the example script above, the %A_%a notation is filled in with the master job ID (%A) and the array task ID (%a).
This is a simple way to create output files in which the file name is different for each job in the array.
There are different ways of specifying array indices, depending on your workload. Examples are shown below:
# A job array with array tasks numbered from 0 to 31.
#SBATCH --array=0-31

# A job array with array tasks numbered 1, 2, 5, 19, 27.
#SBATCH --array=1,2,5,19,27

# A job array with array tasks numbered 1, 3, 5 and 7.
#SBATCH --array=1-7:2
To cancel an entire array job:
scancel <Job ID Number>To cancel a specific task in an array job:
scancel <jobid>_<taskid>To cancel a range of specific tasks in an array job:
scancel <jobid>_[<taskid>_<taskid>]
Job dependencies
The sbatch can also be utilised to assist workflows that involve multiple steps or when you are using checkpoints:
the --dependency option allows you to launch jobs on the condition of completion (or successful completion) of another job.
To submit a job to start after the completion of specified job the following can be used: sbatch --dependency=afterok:<Job Number> <Job script>.
For example, the below submits the jobs script dependant_job.sub so that it will only start upon the completion of job number, 106178.
[abc123@costar-login01 ~]$ sbatch --dependency=afterok:106178 dependant_job.sub
Note
More information on building Slurm job pipelines using dependencies is shown here: https://hpc.nih.gov/docs/job_dependencies.html
Benchmarking and scaling
Benchmarking and scaling are important for running simulations on HPC clusters. They help you maximise throughput and minimise wasted resources.
Before running production workloads, benchmark your problem across a range of core counts to identify the most efficient resource request.
Below are plots from a benchmarking exercise of a DFT B3LYP energy calculation for two molecules:
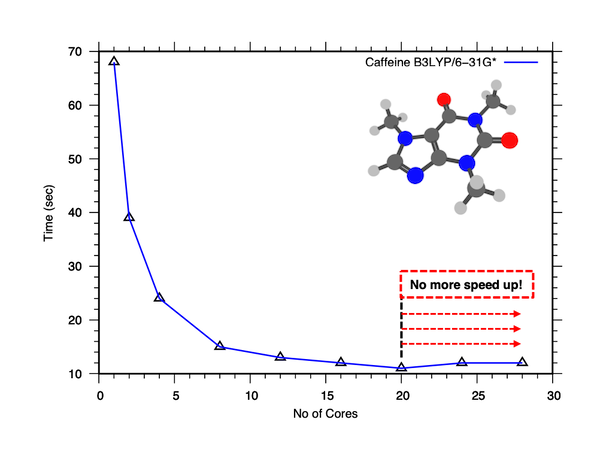
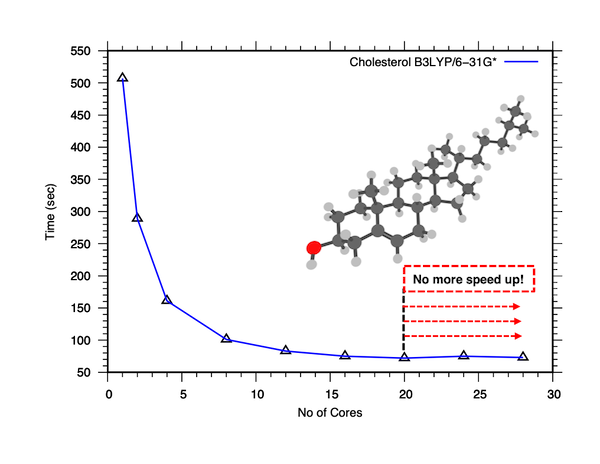
Both plots show runtime versus number of cores. Performance improves up to about 20 cores in both cases.
Beyond 20 cores there is no improvement in these examples, so requesting more cores provides no benefit.
In fact, requesting more cores in your Slurm job script would:
Waste resources that could be allocated to another job.
Potentially slow the calculation due to parallel overhead (sometimes producing U-shaped scaling curves).
Tip
Having the scaling of your problem for every simulation is not necessary, but using model problems to inform yourself is a very good idea, so you can gauge the correct amount of resources to request when running day to day jobs.